What's new from the lab
Short, readable summaries of our newest publications — the methods, the findings, and why they matter. Ready to download, read, and cite.
28 summaries

CVE-2026-98432: The Linux Kernel Patch Shipped. The Bug Did Not Go Away.
An independent reproduction study of the critical IPv4/TCP use-after-free that Anthropic's Frontier Red Team found and exploited — confirming the vulnerable code is still present in the source and explaining how to verify whether your own kernel is actually patched.
Read the summary →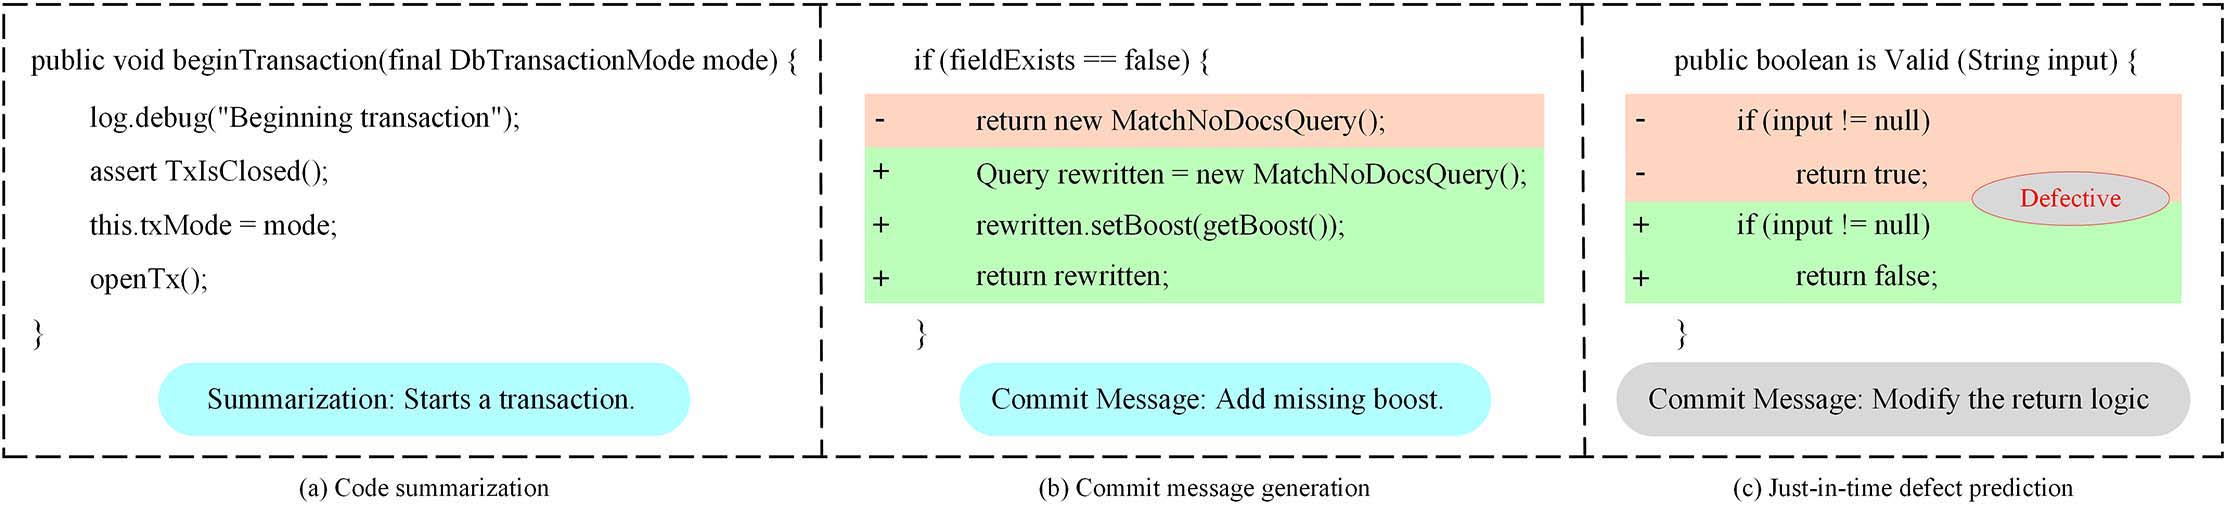
When Does Parameter-Efficient Fine-Tuning Beat Full Fine-Tuning in Code-Change Learning?
The first systematic comparison of PEFT (LoRA, adapters, prompt tuning) against full-model fine-tuning across seven code LMs on real code-change tasks — plus PastaK, a probing-guided framework that trains only a fraction of the parameters and still beats full fine-tuning.
Read the summary →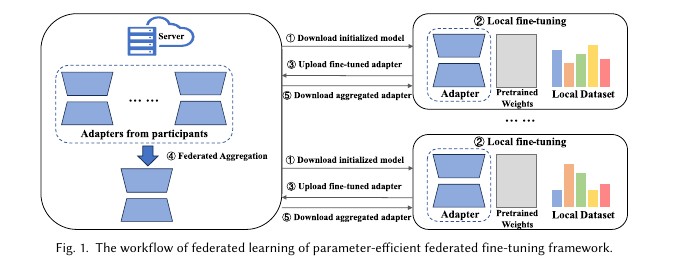
Federated fine-tuning lets companies fix bugs together without sharing code
LLM-based automated program repair depends on high-quality code — but most real-world code is proprietary. This study applies federated learning to fine-tune LLMs on a private industrial dataset (TutorCode) for program repair, evaluated on the EvalRepair-Java benchmark, and finds federated fine-tuning significantly improves repair while preserving data privacy.
Read the summary →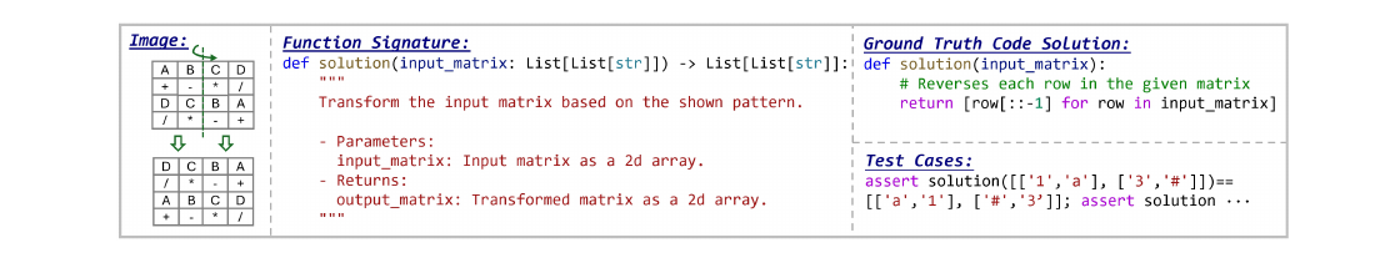
Top models score under 37% on HumanEval-V — visual reasoning, not coding skill, is the bottleneck
HumanEval-V is a benchmark of 253 human-annotated tasks that push large multimodal models to read an algorithm's logic straight from a diagram and emit working Python. Across 27 state-of-the-art LMMs, the best result is only 36.8% pass@1. The authors show the real failure point is high-level visual reasoning, not coding ability.
Read the summary →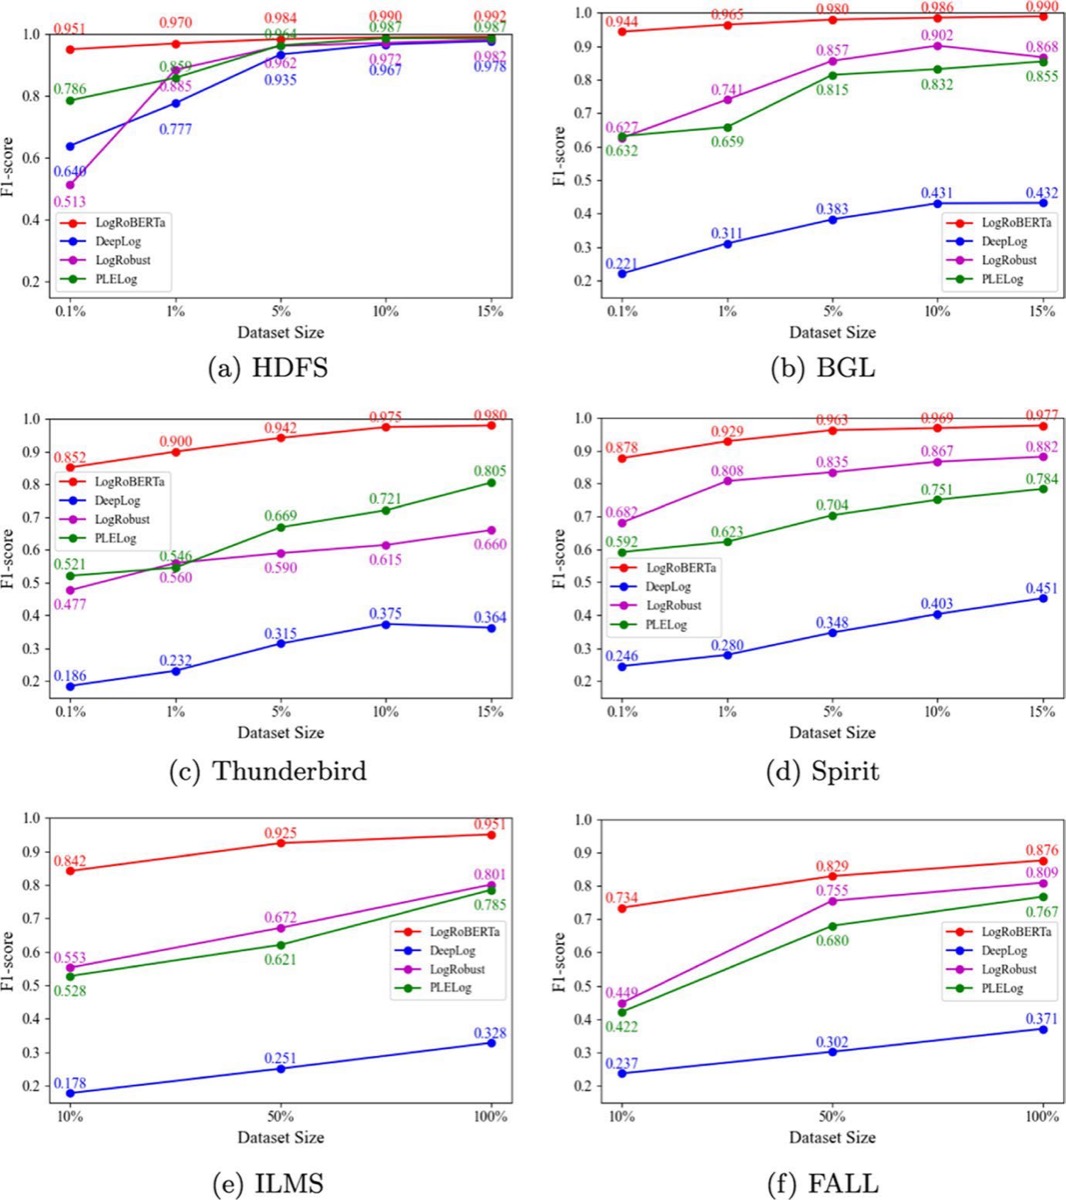
LogRoBERTa: Hybrid Language Model Detects Log Anomalies Without a Parser
Anomaly detection in software logs usually leans on time-consuming log parsers. LogRoBERTa discards the parser entirely, pairing RoBERTa's contextual embeddings with an attention-based BiLSTM. A Determinantal Point Process (DPP) sampler builds a small, diverse labeled set — just 20,000 logs on BGL (0.42% of the dataset). Across HDFS, BGL, Thunderbird, and Spirit it outperforms state-of-the-art baselines including three fully supervised models, stays strong on low-resource data, and cuts runtime by roughly a third.
Read the summary →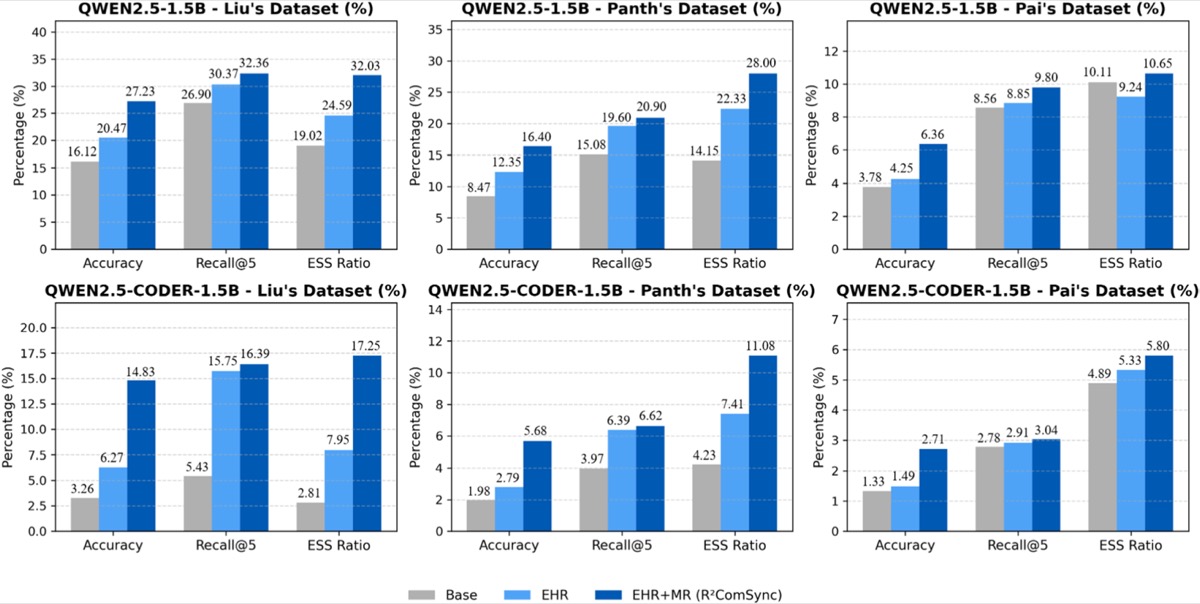
R2ComSync harnesses LLMs to automatically keep code comments in sync
R2ComSync is a Large Language Model (LLM) framework for Code-Comment Synchronization (CCS): automatically rewriting an outdated comment when its code changes. A pilot study showed vanilla LLMs fall short of state-of-the-art CCS methods. R2ComSync closes two gaps: Ensemble Hybrid Retrieval (EHR), which mixes code-comment semantic similarity with code-change-pattern similarity to build instructive in-context examples, and a Multi-turn Re-ranking (MR) strategy that prioritizes the most correct-prone candidates.
Read the summary →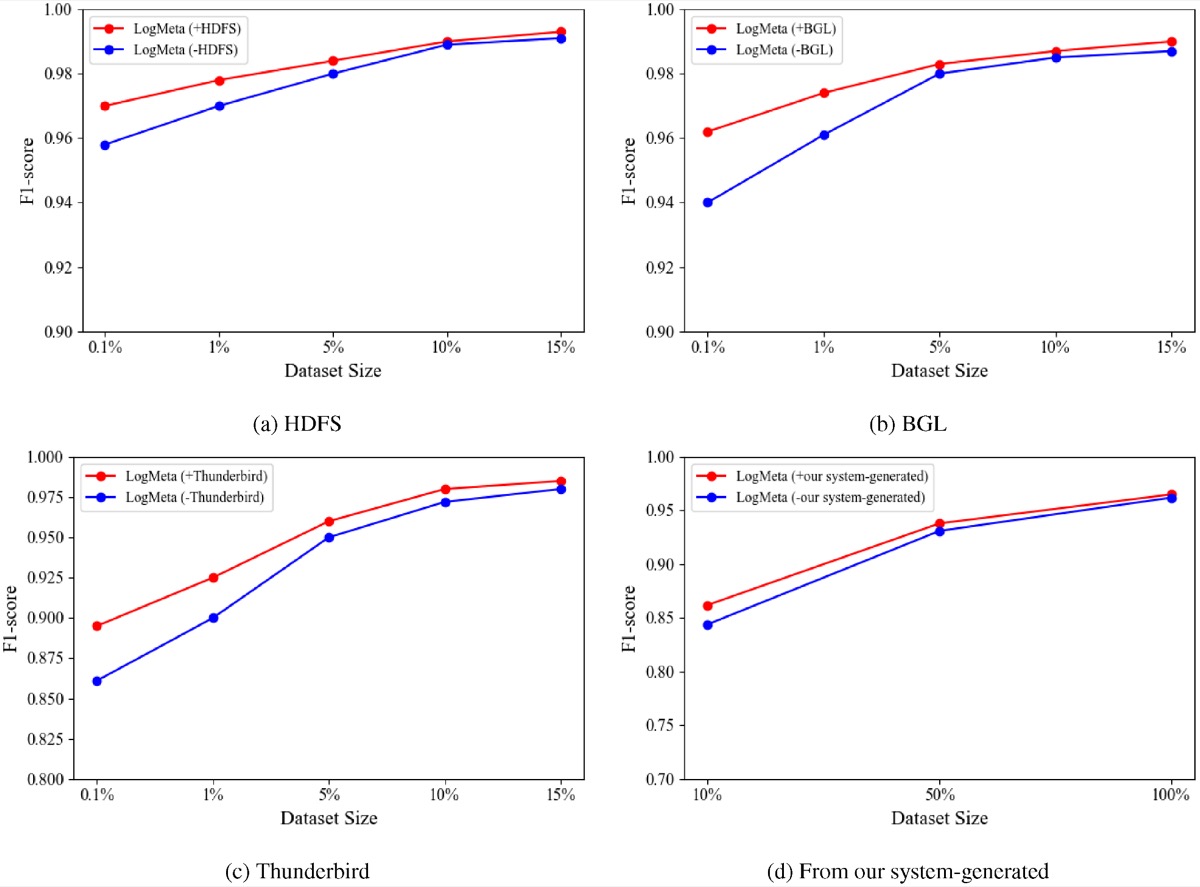
LogMeta: few-shot meta-learning for log anomaly detection that adapts to new systems
Deep log-anomaly detectors struggle with heterogeneous log formats and scarce labeled anomalies. LogMeta combines Model-Agnostic Meta-Learning (MAML) with a hybrid language model — RoBERTa for semantics plus Bi-LSTM and attention for sequence dependencies — so it adapts to unseen systems from a few samples.
Read the summary →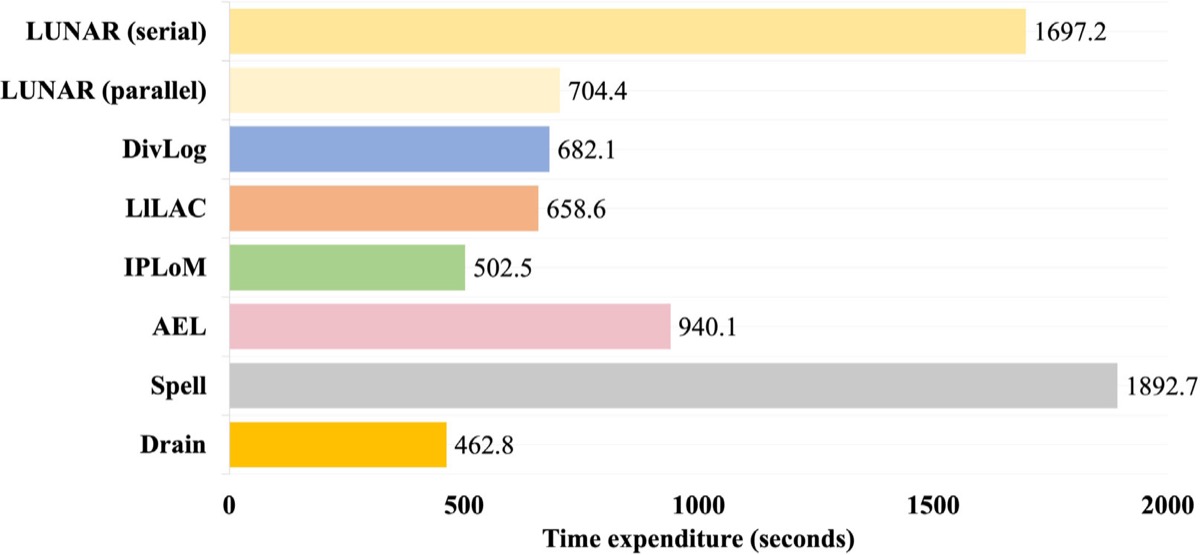
Benchmark wins don't transfer: a task-oriented re-evaluation of log parsing and anomaly detection on real industrial logs
This study re-evaluates seven log parsers and five anomaly-detection models on real industrial logs (factory assembly, process control, SCADA) versus a curated benchmark. Nearly everything degrades on industrial data, LLM-based parsers win on accuracy, and improving parsing rarely flows through to better detection — a call to measure the pipeline end-to-end.
Read the summary →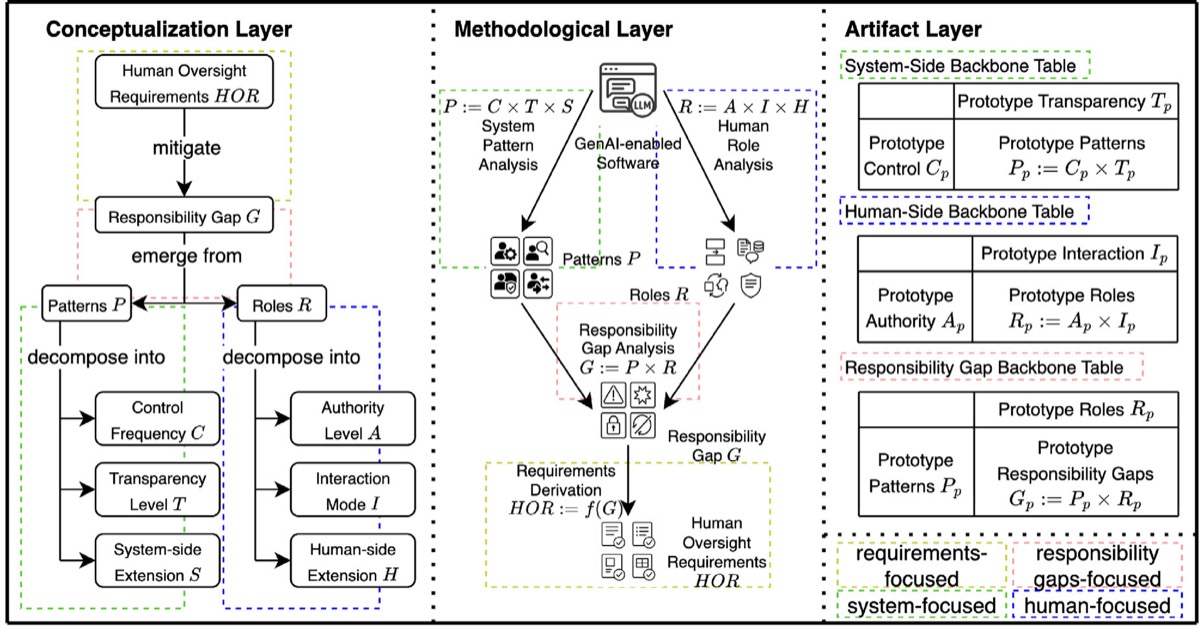
Bridging the responsibility gap: deriving human-oversight requirements for GenAI-enabled software
As generative AI becomes an active component of reasoning and decision support, accountability becomes diffuse: developers can't see how models reach conclusions, users can't fully control behavior, organizations struggle to trace decisions. The authors argue human oversight should be formalized as an explicit category in requirements engineering, and propose a design methodology that identifies responsibility gaps by aligning system-side patterns (control, transparency) with human-side roles (authority, interaction), then derives oversight requirements and documents the reasoning in a reusable Deductive Backbone Table.
Read the summary →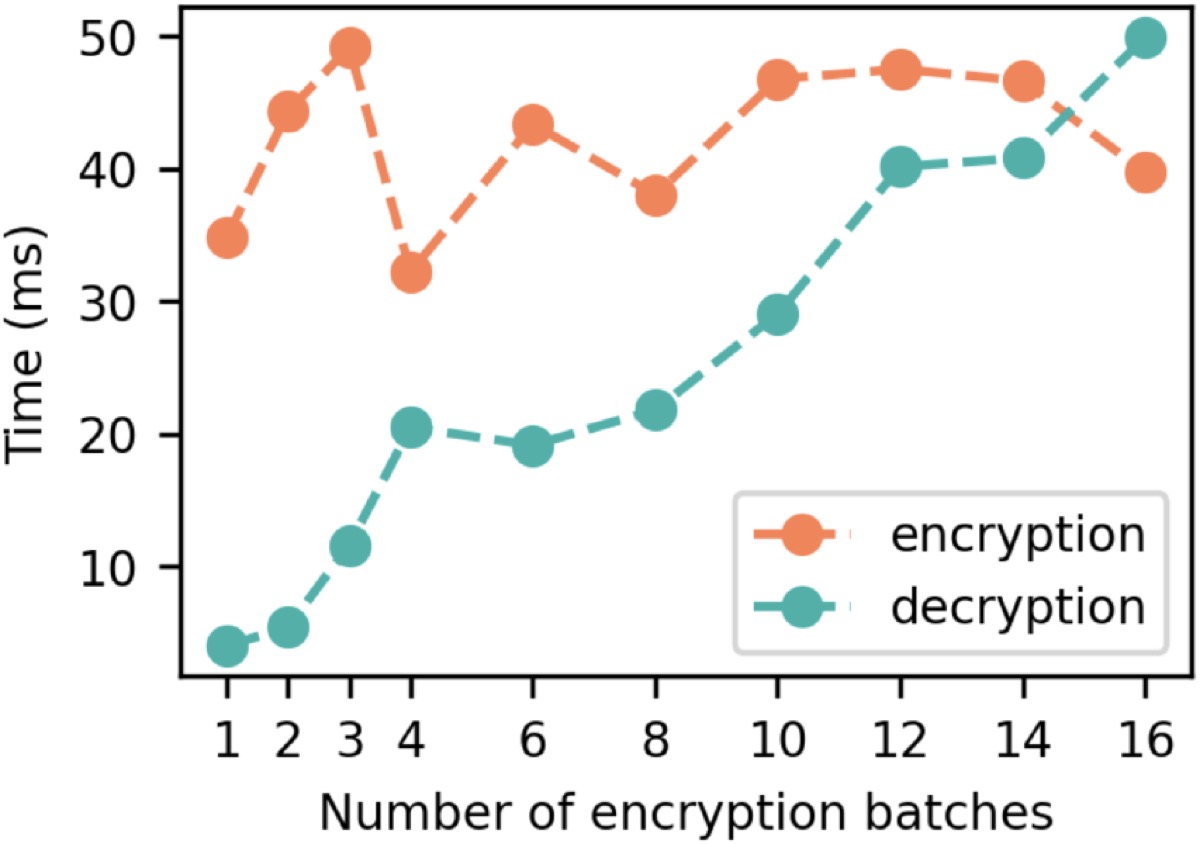
FedDC: dual-layer protection that keeps federated learning accurate against black-box and white-box attacks
FedDC pairs differential privacy with a chaos-logistic-map scrambler, protecting only sensitive layers (not the whole model). Against black-box theft it drags accuracy to 9–12%; against white-box model inversion it raises reconstruction error dramatically — all with under 2.3–5% per-round overhead.
Read the summary →AI decision support nearly triples fraud-detection odds — but vulnerability is age- and scam-specific
Most fraud research describes WHO is vulnerable via static risk profiles or single-scam studies; this paper tests whether real-time AI support reduces fraud risk at the moment of exposure, and how its effects differ across age and scam type. Grounded in the Person–Task Fit framework, a 2×2 online lab-in-the-field experiment compared AI-assisted vs. unaided judgment across younger (18–30) and older (50+) groups over 10 days using ecologically realistic simulated fraud scenarios across six scam categories. AI-assisted support improved detection accuracy and reduced risky intention, but vulnerability was patterned rather than uniform — and AI produced the largest reductions exactly in each group's most-vulnerable scam categories.
Read the summary →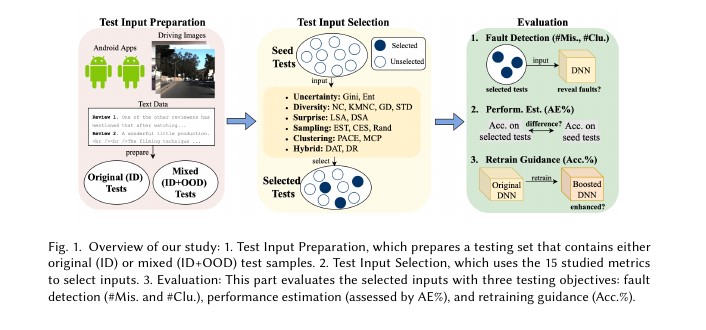
Which test-selection metric actually helps? 1,640 scenarios say: it depends on your objective
This empirical study benchmarks 15 test-selection metrics on 1,640 scenarios spanning three testing objectives, five out-of-distribution shift types, three data modalities (Android, image, text) and 13 Deep Neural Networks. The winners are often not the metrics designed for the job — diversity-based metrics dominate performance estimation.
Read the summary →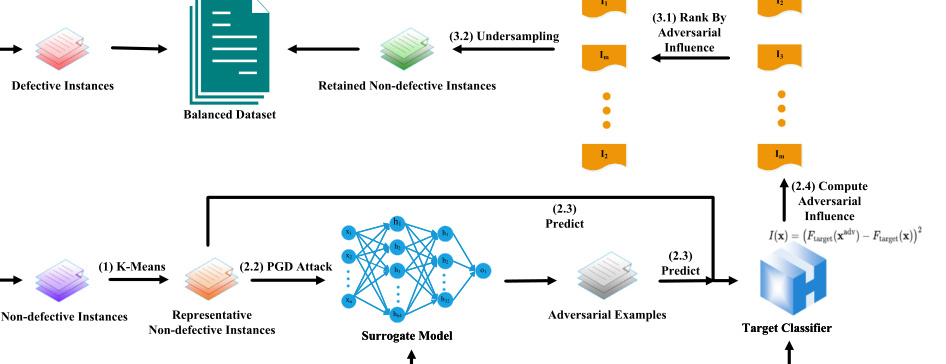
Keeping the Most Important Data, Not the Most: A Smarter Fix for Imbalanced Defect Prediction
AIIUS keeps the clean modules that shape a defect classifier boundary, lifting Balance, AUC and MCC across 18 datasets.
Read the summary →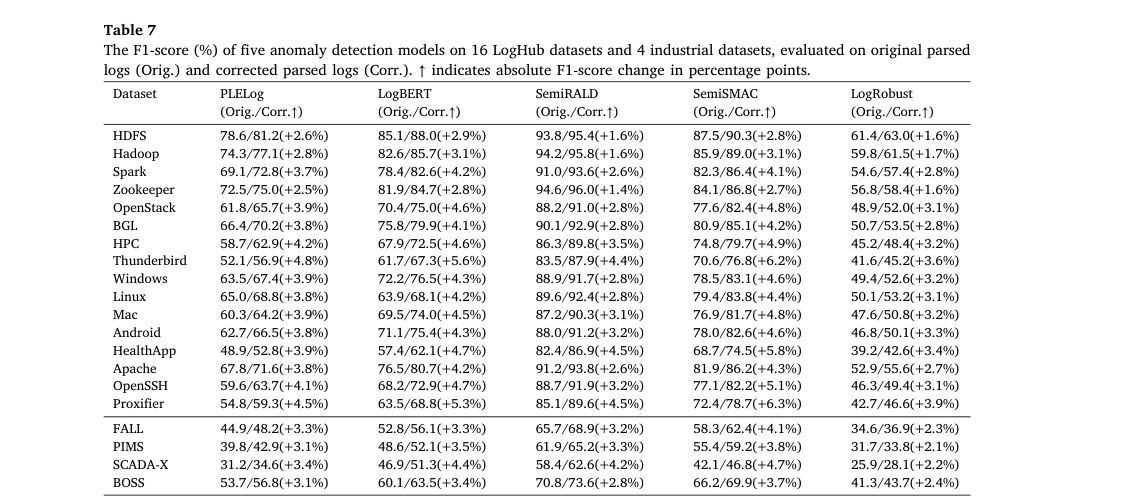
When parsing goes wrong: How tiny log parsing mistakes quietly break AI anomaly detection
Small log parsing errors silently degrade AI anomaly detection; fixing them yields reliable gains for software reliability.
Read the summary →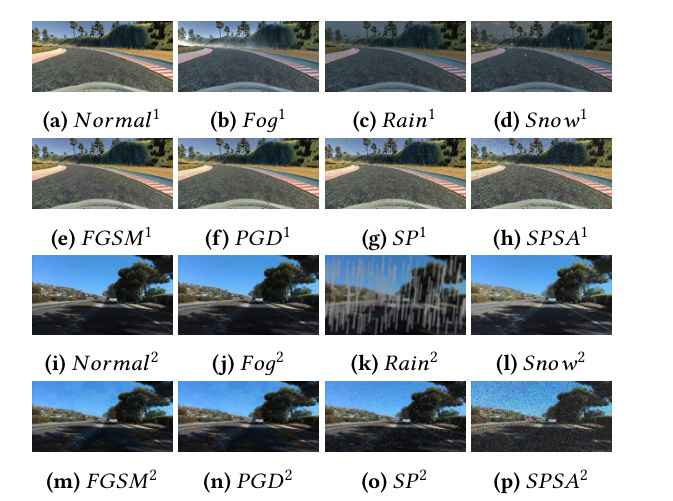
Benchmarking Which Safety Nets Catch Self Driving Cars When the World Gets Unfamiliar
Nine detectors are tested against seven unfamiliar driving conditions on simulated and real roads, naming the most reliable safety net.
Read the summary →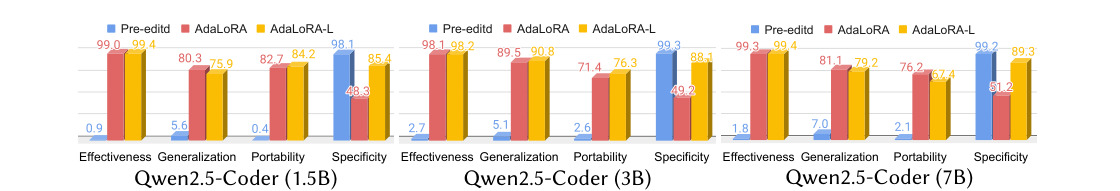
Surgical Model Editing Keeps Code LLMs Current Without the Cost of Retraining
A lightweight model editing method corrects deprecated API recommendations in code LLMs in seconds, no retraining.
Read the summary →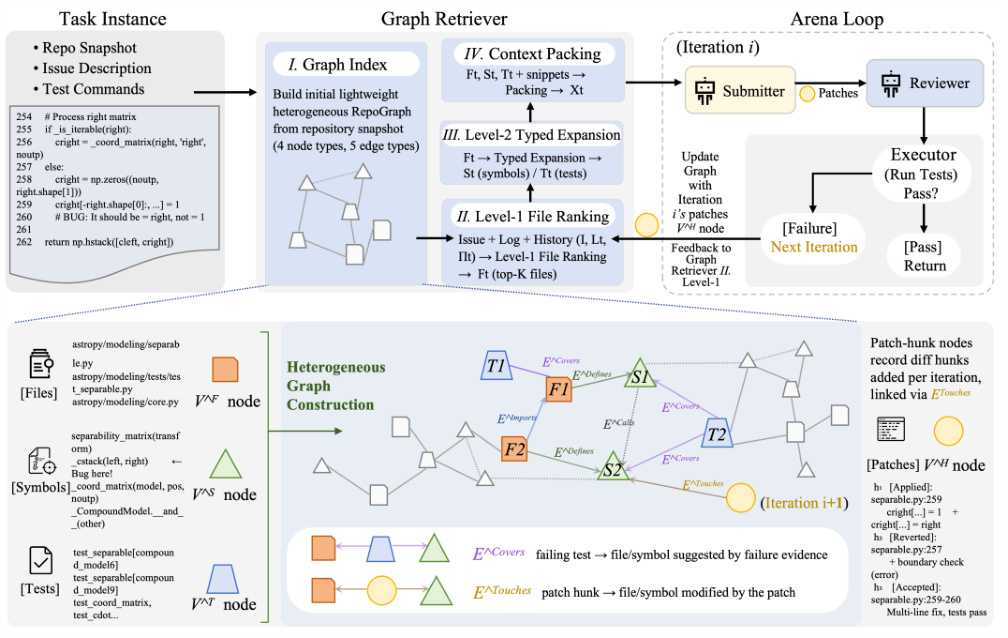
HGARena Teaches AI Agents to Fix Real GitHub Bugs on a Budget
A budgeted, test driven multi-agent framework with graph-augmented retrieval resolves real GitHub issues efficiently.
Read the summary →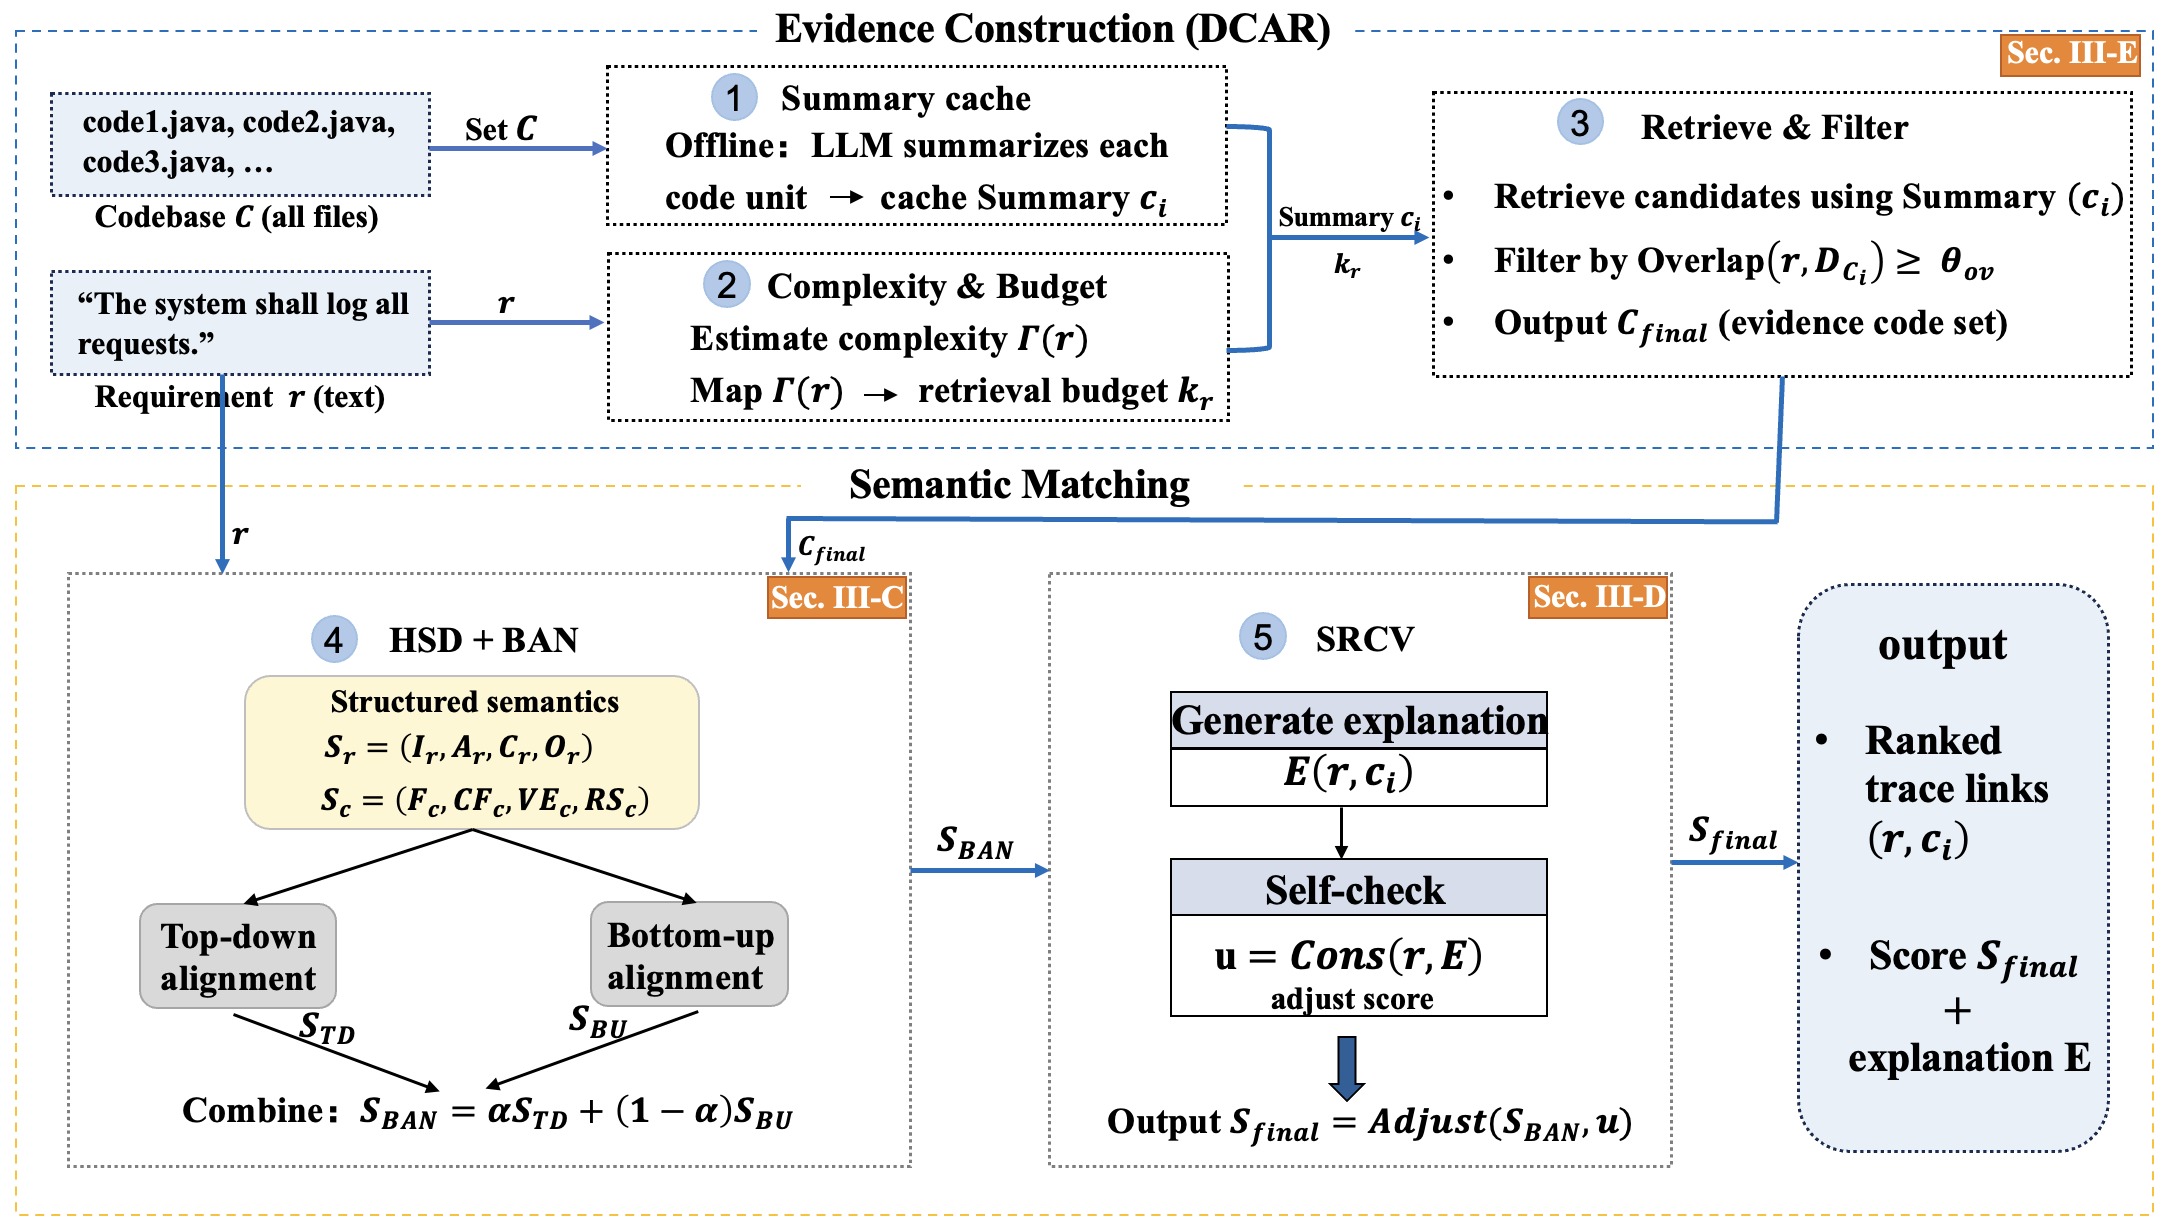
Making Traceable AI Code Links Work With 7.4 Percent Better Accuracy and 41.7 Percent Fewer Tokens
A self-reflective LLM framework improves requirement to code traceability links while costing far fewer tokens.
Read the summary →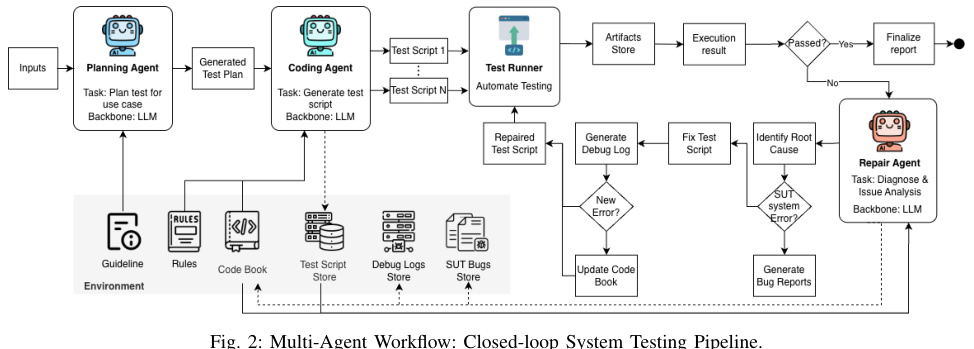
Raising Black Box Test Reliability From 39 Percent to 84 Percent for Regulated Insurance Software
Artifact-constrained LLM agents test complex regulated software as a black box, lifting reliability dramatically.
Read the summary →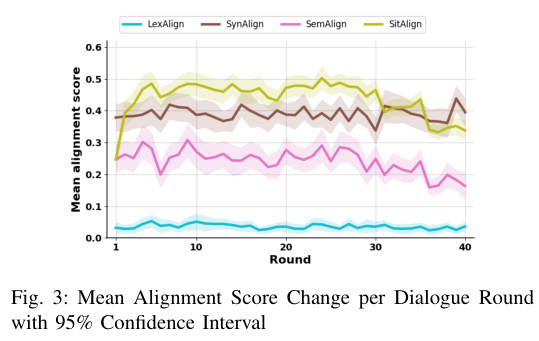
Reading the Room: How Four Alignment Signals Expose a Scam Before the Money Request
Tracking four levels of conversational alignment lifts scam detection F1 from 0.61 to 0.82 in a user study.
Read the summary →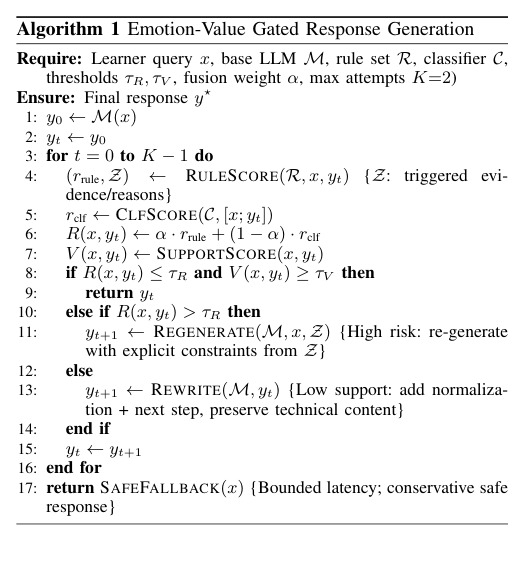
When AI Tutors Go Cold: Making Large Language Models Emotionally Safe for Students
A non-invasive, emotion-aware intervention reduces emotionally risky responses in 42,172 real student AI interactions.
Read the summary →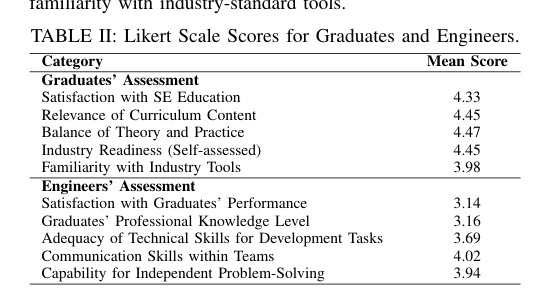
Graduates Rate Themselves 4.45 for Job Readiness. Their Employers Say 3.14.
A mixed method study exposes the gap between software engineering graduates' self perception and industry expectations.
Read the summary →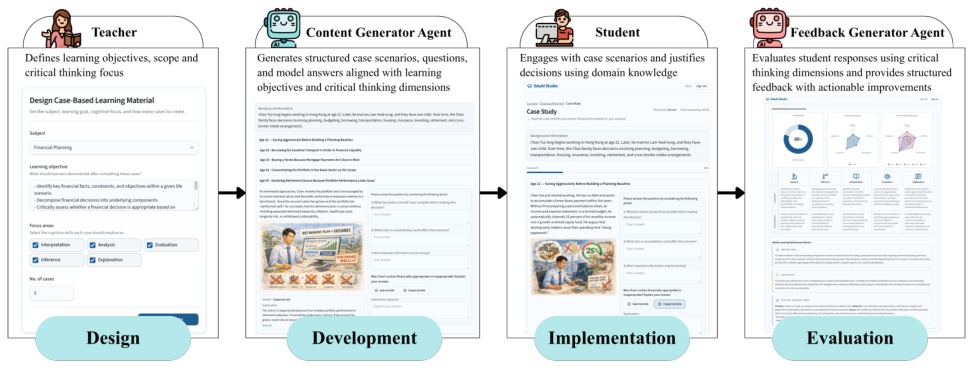
A Closed Loop for Clearer Thinking: How Two LLM Agents Tutor Critical Thinking
Two specialized LLM agents in a closed loop learning framework significantly improved 38 students' critical thinking.
Read the summary →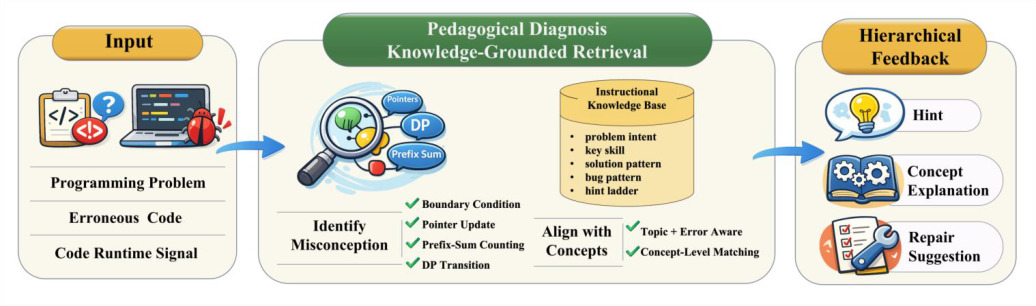
AI That Teaches Instead of Fixes: A Three Level Feedback Framework for Learning to Code
Knowledge-augmented hierarchical feedback that teaches novice programmers the concept, not just the correction.
Read the summary →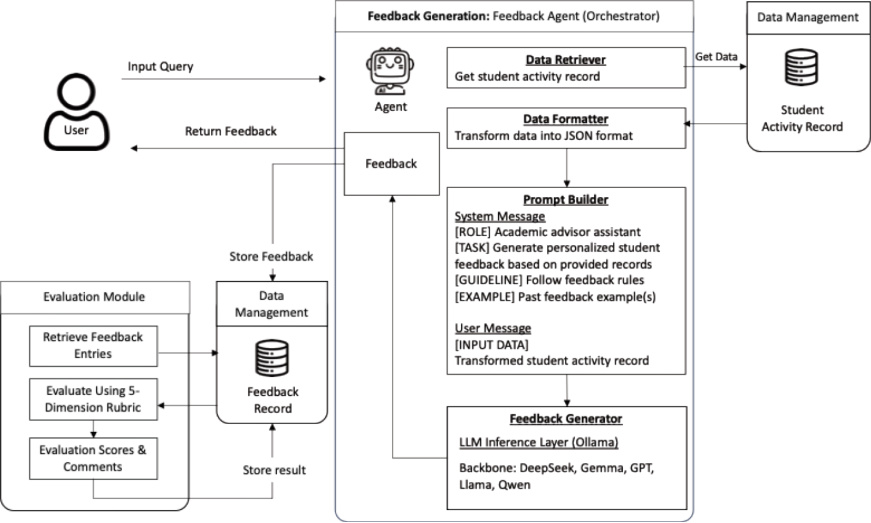
LLM Feedback That Scales Beyond Grades
An LLM feedback agent drafts professional holistic student feedback from activity records, evaluated on five quality dimensions across five local models.
Read the summary →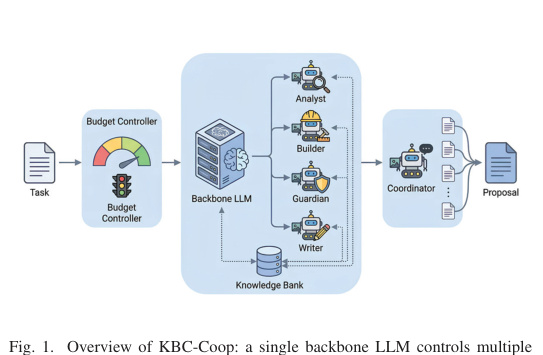
One Model, Many Minds: Knowledge Grounding Makes LLM Teamwork Actually Work
A knowledge and budget controlled cooperation framework turns a single backbone LLM into a grounded team of specialist roles.
Read the summary →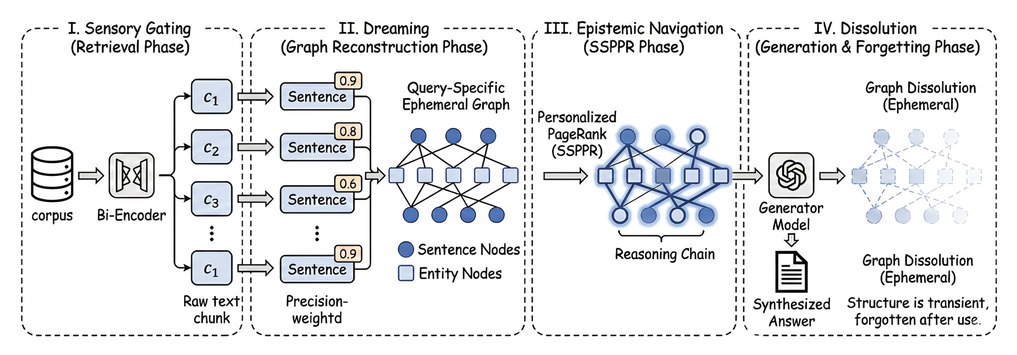
A Graph Built for One Question and Then Forgotten
Transient RAG builds a query specific ephemeral graph at inference time, improving counterfactual reasoning without index maintenance.
Read the summary →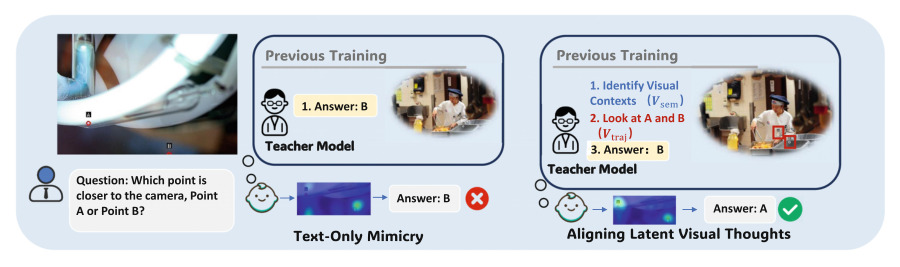
Teaching Small AI Models to Look Before They Speak: LaViT Closes the Perception Gap
Aligning latent visual thoughts lets a compact 3B multimodal model match far larger models on complex visual reasoning.
Read the summary →