
Top models score under 37% on HumanEval-V — visual reasoning, not coding skill, is the bottleneck
On a new 253-task benchmark where models must turn diagrams into working code, Claude 3.5 Sonnet reaches just 36.8% pass@1, Pixtral 124B gets 21.3%, and many open-weight models fall below 10%.
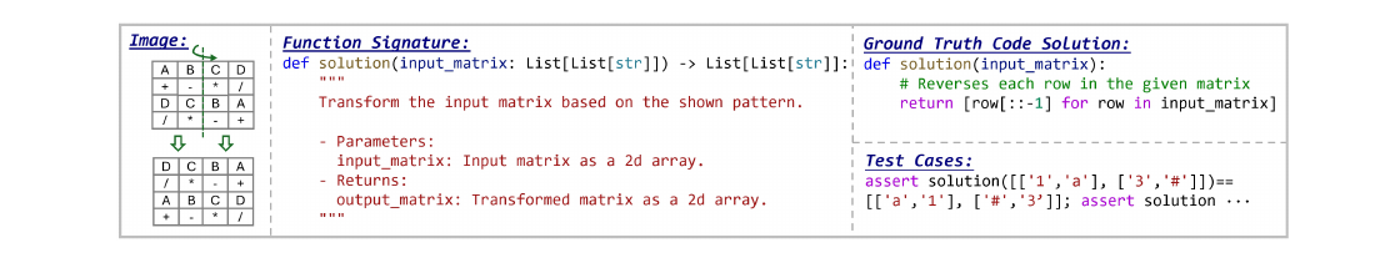
HumanEval-V is a benchmark of 253 human-annotated tasks that push large multimodal models to read an algorithm's logic straight from a diagram and emit working Python. Across 27 state-of-the-art LMMs, the best result is only 36.8% pass@1. The authors show the real failure point is high-level visual reasoning, not coding ability.
Why it matters
While recent advances in Large Multimodal Models (LMMs) have demonstrated impressive visual capabilities across various domains, their visual reasoning abilities in coding contexts remain largely unexplored.
Key findings
- Dataset & effort 253 human-annotated code-generation tasks across 6 visual categories, built from >800 hours of annotation (4 annotators × 200 hours); 100 seed problems were recreated and diversified into 253 tasks.
- Headline result Top-performing LMMs are weak on the task: Claude 3.5 Sonnet and Pixtral 124B reach only 36.8% and 21.3% pass@1, while many open-weight models score below 10%.
- Vision-to-code is the bottleneck Models do best when visual understanding and code generation are decoupled (V2T2C w/ GPT-4o: Claude 3.5 Sonnet 43.7% pass@3 vs 28.1% pass@1 in direct V2C), showing vision-to-code alignment is a major gap.
- Coding ability is NOT the problem Given human-written problem specifications, GPT-4o jumps to 96.5% pass@3 (vs 40.5% in V2T2C); with only function signatures (no diagram/description), five proprietary models score 0%.
- Weak link to existing benchmarks Models that top general benchmarks collapse on HumanEval-V — e.g. Claude 3.5 Sonnet scores 81.2 AI2D, 81.7 MMBench and 67.7 MathVista but only 43.7% on HumanEval-V, exposing blind spots in multimodal evaluation.
HumanEval-V
- Task format: each task pairs a single self-contained diagram encoding the algorithmic logic with a Python function signature (inputs/return type) and a set of test cases — minimal textual description by design.
- Construction: a four-step manual pipeline — collect/screen problems (Codeforces, LeetCode, GeeksforGeeks, Stack Overflow), distill the visual essence, recreate 100 seed tasks, then diversify with GPT-4o into 253 tasks.
- Taxonomy: six visual task types (Iteration, Aggregation, Expansion, Validation, Computation, Rearrangement) and six capability dimensions.
- Evaluation framework: four pipelines — V2C, V2C w/ CoT, V2T2C, and V2T2C w/ GPT-4o (decoupled: a strong coder generates code from a model-written diagram description) — reported as pass@1/pass@3 and scaled to pass@100.
What it means for practitioners
Don't trust general multimodal benchmarks when picking an LMM for visual-programming work: HumanEval-V scores map poorly onto them. Expect even state-of-the-art models to fail on diagrams encoding spatial transforms, topological relations and dynamic patterns; hallucinated visual details are common. Two-stage pipelines (have the model describe the diagram, then generate code with a strong coder) markedly lift performance, as does execution-based feedback for iterative self-correction.
Get the paper & cite it
Official citation: Fengji Zhang, Linquan Wu, Huiyu Bai, Guancheng Lin, Xiao Li, Xiao Yu, Yue Wang, Bei Chen, Jacky W. Keung (2026). HumanEval-V: Systematic Evaluation of Visual Reasoning in Large Multimodal Models for Code Generation. ACM Transactions on Software Engineering and Methodology. DOI: 10.1145/3813804.