Surgical Model Editing Keeps Code LLMs Current Without the Cost of Retraining
Code assistants powered by large language models often keep recommending APIs that libraries have already retired, because their training data is out of date. Instead of retraining a whole model, this work surgically edits only the layers that store the knowledge for one API, bringing a model up to date in seconds while leaving everything else untouched.
Code assistants powered by large language models often keep recommending APIs that libraries have already retired, because their training data is out of date. Instead of retraining a whole model, this work surgically edits only the layers that store the knowledge for one API, bringing a model up to date in seconds while leaving everything else untouched.
Why it matters
Large language models trained on code learn from snapshots of real projects. When a library replaces torch.svd with torch.linalg.svd, the model keeps recommending the old call, even though the old call will soon stop working. Prior work found that over 37 percent of one popular model's API predictions pointed at deprecated APIs, so stale recommendations are frequent, not rare. Each one can quietly break a build or hand developers code that will not survive the next library update.
The obvious fix, retraining the model on fresh code, is like using a cannon to kill a fly. Retraining a modern code model is slow and expensive, and libraries update constantly, so it is impractical to repeat it every time an API changes. Model editing offers a lighter path: change only the small slice of knowledge that is wrong. This work shows that the right editing target matters, and that a targeted edit can lift a model from near zero accuracy on up to date API calls to near perfect, in a few seconds on one GPU.
Key findings
- First systematic benchmark The authors build EDAPIBench, the first benchmark for editing deprecated API knowledge in code LLMs, covering over 70 deprecated APIs from 8 popular Python libraries and more than 3,000 editing instances.
- Real code scale They mine 65,596 real functions from GitHub that call up to date APIs, then keep only the prompts where the original model actually outputs the deprecated API, giving over 900 genuine editing instances per model.
- Ten methods, three models They compare 10 state of the art model editing techniques across three open source code LLMs, Qwen2.5 Coder, CodeGemma, and DeepSeek Coder.
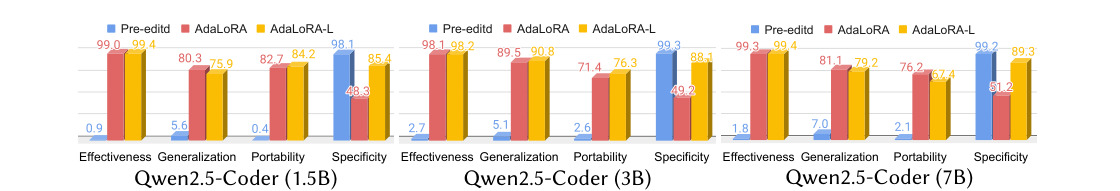
- Effectiveness leap AdaLoRA lifts API recommendation accuracy from roughly 1 to 3 percent before editing to 98 to 99 percent after editing on all three models.
- Specificity gain The proposed AdaLoRA L improves Specificity, which measures how well unrelated knowledge is preserved, by 79.1, 67.6, and 45.5 percent across the three models.
- Single GPU, seconds One edit completes within a few seconds on a 24 GB GPU; AdaLoRA L averages 3.8 seconds per edit versus 4.8 seconds for AdaLoRA because it touches fewer parameters.
- Low inference cost AdaLoRA L generates a corrected completion in 0.87 to 1.56 seconds per sample, roughly half the 1.83 to 3.31 seconds needed by the replacement based method REPLACEAPI.
- Coding ability preserved After editing, HumanEval pass@1 stays essentially unchanged, 46.3, 31.7, and 29.3 percent versus 46.9, 31.1, and 29.9 percent before editing, whereas plain AdaLoRA drops it to 36.6, 23.7, and 26.2 percent.
- Parameter correct code AdaLoRA L beats the replacement baseline by 41.1 to 76.4 percent in exact match on effectiveness data, because it updates knowledge inside the model rather than only swapping an API name.
- Works across model sizes The Specificity improvement holds consistently for Qwen2.5 Coder at 1.5B, 3B, and 7B scales, so the method does not depend on model size.
Correct API knowledge in seconds, not a full retrain
- EDAPIBench: first benchmark for editing deprecated API knowledge, 70+ APIs across 8 Python libraries
- AdaLoRA L lifts API recommendation accuracy to 98 to 99 percent from a baseline of about 1 to 3 percent
- Specificity improves by up to 79 percent while coding ability measured by HumanEval is preserved
- One edit runs in a few seconds on a single GPU, versus costly full model retraining
- Half the inference cost of replacement based approaches for interactive code completion
What it means for practitioners
For teams shipping code assistants backed by open source models, this work makes continuous API freshness affordable. Instead of retraining a model each time a library changes, you edit only the layers that hold knowledge for the affected API. The edit runs in seconds on one GPU and the onetime layer identification is amortized to about 0.1 second per edit, so it can be run as part of a regular maintenance cycle.
The method also fits interactive settings like IDE autocomplete. Because it fixes knowledge inside the model, it produces the API in a single pass at roughly half the inference cost of detection and regeneration approaches, and it tends to generate complete parameter correct calls rather than only swapping a name. Teams should still reach for non invasive name swap approaches when the model is closed source or when preserving unrelated behavior matters above all else.
Related reading
Get the paper & cite it
Official citation: Guancheng Lin, Xiao Yu, Jacky Keung, Xing Hu, Xin Xia, Alex X. Liu (2026). Don't Use a Cannon to Kill a Fly: Lightweight Model Editing for LLMs to Correct Deprecated API Recommendations. Proceedings of the ACM on Software Engineering. DOI: 10.1145/3832130.